RosaBioinfo
Inter-group and intra-group statistics of expression of pWCP genes in Wolbachia endosymbiont of Culex using RNASeq TPM metric
Mateo Jarry
2026-01-22
- Obtain mean coverage, FPKM and TPM values on the pWCP plasmid from our whole-genome alignments
- Data loading
- Data formatting
- Sample batch characterization
- Inter-group statistics
- Intra-group statistics
- Boxplot by group
Obtain mean coverage, FPKM and TPM values on the pWCP plasmid from our whole-genome alignments
We collected mean coverage, TPM and FPKM values for each plasmid gene
for each deduplicated .bam files (UMI-unique) using stringtie.
for f in deduplicated*.bam; do
    stringtie -G Data/pWCP.gff $f > result_stringtie_$f.txt
done
In the first part of the Notebook (until “Inter-group statistics”), mean coverage, FPKM and TPM are loaded. However, for all of our analyzes, only TPM values were used (after “Inter-group statistics”).
Data loading
library(dplyr)
library(tidyr)
setwd('./Data/result_stringtie/')
temp <- list.files(pattern = glob2rx("result_stringtie*NG*.txt"), full.names=T)

myfiles <- lapply(temp, read.table, skip = "#", sep="\t")
myfiles <- lapply(myfiles, function(x) separate(x, "V9", c('V9', 'V10', 'V11', 'V12', 'V13', 'V14'), sep = ";"))

myfiles <- lapply(myfiles, function(x) filter(x, x$V1=='pWCP')) # plasmid
names(myfiles) <- temp
head(myfiles[[1]])
##     V1        V2         V3   V4   V5   V6 V7 V8             V9
## 1 pWCP StringTie transcript    1  138 1000  +  . gene_id STRG.1
## 2 pWCP StringTie       exon    1  138 1000  +  . gene_id STRG.1
## 3 pWCP StringTie transcript  226 1174 1000  +  . gene_id STRG.2
## 4 pWCP StringTie       exon  226 1174 1000  +  . gene_id STRG.2
## 5 pWCP StringTie transcript 1381 1879 1000  +  . gene_id STRG.3
## 6 pWCP StringTie       exon 1381 1879 1000  +  . gene_id STRG.3
##                       V10                  V11                  V12
## 1  transcript_id STRG.1.1  reference_id dnaB2b       cov 267.891296
## 2  transcript_id STRG.1.1        exon_number 1  reference_id dnaB2b
## 3  transcript_id STRG.2.1   reference_id is110        cov 34.983139
## 4  transcript_id STRG.2.1        exon_number 1   reference_id is110
## 5  transcript_id STRG.3.1   reference_id dnaB1       cov 108.479362
## 6  transcript_id STRG.3.1        exon_number 1   reference_id dnaB1
##                   V13               V14
## 1  FPKM 145836.500000  TPM 82594.851562
## 2      cov 267.891296
## 3   FPKM 19044.359375  TPM 10785.820312
## 4       cov 34.983139
## 5   FPKM 59054.742188  TPM 33445.792969
## 6      cov 108.479362
# Delete rows containing “exon” in any column
myfiles <- lapply(myfiles, function(x) {
  x[!apply(x, 1, function(row) any(grepl("exon", row, ignore.case = TRUE))), ]
})
head(myfiles)
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_10_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 7367 8060 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.15
## 31 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.16
##                         V10                  V11             V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b  cov 267.891296
## 3    transcript_id STRG.2.1   reference_id is110   cov 34.983139
## 5    transcript_id STRG.3.1   reference_id dnaB1  cov 108.479362
## 7    transcript_id STRG.4.1   reference_id relE1   cov 45.236591
## 9    transcript_id STRG.5.1   reference_id relB1   cov 94.227463
## 11   transcript_id STRG.6.1    reference_id gp05  cov 841.379822
## 13   transcript_id STRG.7.1    reference_id gp06  cov 413.470703
## 15   transcript_id STRG.8.1    reference_id gp07  cov 264.941162
## 17   transcript_id STRG.9.1    reference_id gp08   cov 21.259481
## 19  transcript_id STRG.10.1    reference_id gp09   cov 29.979359
## 21  transcript_id STRG.11.1    reference_id parA   cov 73.819847
## 23  transcript_id STRG.12.1    reference_id gp11  cov 481.095520
## 25  transcript_id STRG.13.1    reference_id gp12   cov 39.585014
## 27  transcript_id STRG.14.1   reference_id relB2  cov 174.390900
## 29  transcript_id STRG.15.1   reference_id relE2   cov 75.273544
## 31  transcript_id STRG.16.1  reference_id dnaB2a  cov 259.472961
##                    V13                V14
## 1   FPKM 145836.500000   TPM 82594.851562
## 3    FPKM 19044.359375   TPM 10785.820312
## 5    FPKM 59054.742188   TPM 33445.792969
## 7    FPKM 24626.207031   TPM 13947.111328
## 9    FPKM 51296.191406   TPM 29051.722656
## 11  FPKM 458036.093750  TPM 259409.859375
## 13  FPKM 225088.000000  TPM 127479.132812
## 15  FPKM 144230.484375   TPM 81685.281250
## 17   FPKM 11573.381836    TPM 6554.612793
## 19   FPKM 16320.369141    TPM 9243.080078
## 21   FPKM 40186.554688   TPM 22759.751953
## 23  FPKM 261902.078125  TPM 148328.875000
## 25   FPKM 21549.560547   TPM 12204.646484
## 27   FPKM 94936.117188   TPM 53767.292969
## 29   FPKM 40977.925781   TPM 23207.947266
## 31  FPKM 141253.671875   TPM 79999.351562
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_11_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 7367 8060 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.15
## 31 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.16
##                         V10                  V11              V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b   cov 444.652161
## 3    transcript_id STRG.2.1   reference_id is110   cov 185.578506
## 5    transcript_id STRG.3.1   reference_id dnaB1   cov 168.853806
## 7    transcript_id STRG.4.1   reference_id relE1   cov 174.541260
## 9    transcript_id STRG.5.1   reference_id relB1   cov 572.345398
## 11   transcript_id STRG.6.1    reference_id gp05  cov 2177.298096
## 13   transcript_id STRG.7.1    reference_id gp06  cov 1297.450195
## 15   transcript_id STRG.8.1    reference_id gp07   cov 580.149658
## 17   transcript_id STRG.9.1    reference_id gp08    cov 57.448528
## 19  transcript_id STRG.10.1    reference_id gp09   cov 106.318573
## 21  transcript_id STRG.11.1    reference_id parA   cov 224.522141
## 23  transcript_id STRG.12.1    reference_id gp11  cov 2780.412842
## 25  transcript_id STRG.13.1    reference_id gp12   cov 164.505768
## 27  transcript_id STRG.14.1   reference_id relB2  cov 1213.079102
## 29  transcript_id STRG.15.1   reference_id relE2   cov 308.517395
## 31  transcript_id STRG.16.1  reference_id dnaB2a   cov 366.937836
##                    V13                V14
## 1    FPKM 71202.289062   TPM 40760.542969
## 3    FPKM 29716.742188   TPM 17011.681641
## 5    FPKM 27038.611328   TPM 15478.554688
## 7    FPKM 27949.345703   TPM 15999.914062
## 9    FPKM 91649.851562   TPM 52465.976562
## 11  FPKM 348651.406250  TPM 199589.390625
## 13  FPKM 207761.093750  TPM 118935.156250
## 15   FPKM 92899.539062   TPM 53181.375000
## 17    FPKM 9199.250977    TPM 5266.213379
## 19   FPKM 17024.826172    TPM 9746.051758
## 21   FPKM 35952.800781   TPM 20581.580078
## 23  FPKM 445228.343750  TPM 254875.937500
## 25   FPKM 26342.359375   TPM 15079.976562
## 27  FPKM 194250.734375  TPM 111200.984375
## 29   FPKM 49402.988281   TPM 28281.291016
## 31   FPKM 58757.867188   TPM 33636.593750
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_13_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 7367 8060 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.15
## 31 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.16
##                         V10                  V11              V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b   cov 436.340607
## 3    transcript_id STRG.2.1   reference_id is110   cov 133.500534
## 5    transcript_id STRG.3.1   reference_id dnaB1   cov 132.032883
## 7    transcript_id STRG.4.1   reference_id relE1   cov 108.530441
## 9    transcript_id STRG.5.1   reference_id relB1   cov 313.838928
## 11   transcript_id STRG.6.1    reference_id gp05  cov 3364.014404
## 13   transcript_id STRG.7.1    reference_id gp06  cov 1521.172119
## 15   transcript_id STRG.8.1    reference_id gp07   cov 544.254333
## 17   transcript_id STRG.9.1    reference_id gp08    cov 61.304840
## 19  transcript_id STRG.10.1    reference_id gp09    cov 83.316742
## 21  transcript_id STRG.11.1    reference_id parA   cov 215.438171
## 23  transcript_id STRG.12.1    reference_id gp11  cov 2861.283691
## 25  transcript_id STRG.13.1    reference_id gp12   cov 118.616714
## 27  transcript_id STRG.14.1   reference_id relB2   cov 997.832397
## 29  transcript_id STRG.15.1   reference_id relE2   cov 227.268204
## 31  transcript_id STRG.16.1  reference_id dnaB2a   cov 307.251373
##                    V13                V14
## 1    FPKM 67570.718750   TPM 37998.355469
## 3    FPKM 20673.589844   TPM 11625.782227
## 5    FPKM 20446.312500   TPM 11497.972656
## 7    FPKM 16806.777344    TPM 9451.282227
## 9    FPKM 48600.382812   TPM 27330.400391
## 11  FPKM 520943.656250  TPM 292952.375000
## 13  FPKM 235565.265625  TPM 132470.000000
## 15   FPKM 84281.992188   TPM 47395.933594
## 17    FPKM 9493.528320    TPM 5338.680664
## 19   FPKM 12902.242188    TPM 7255.568848
## 21   FPKM 33362.265625   TPM 18761.251953
## 23  FPKM 443091.906250  TPM 249172.484375
## 25   FPKM 18368.714844   TPM 10329.636719
## 27  FPKM 154522.062500   TPM 86895.398438
## 29   FPKM 35194.238281   TPM 19791.460938
## 31   FPKM 47580.253906   TPM 26756.726562
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_14_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 7367 8060 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.15
## 31 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.16
##                         V10                  V11              V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b   cov 408.297089
## 3    transcript_id STRG.2.1   reference_id is110   cov 114.949417
## 5    transcript_id STRG.3.1   reference_id dnaB1    cov 87.960617
## 7    transcript_id STRG.4.1   reference_id relE1   cov 147.626923
## 9    transcript_id STRG.5.1   reference_id relB1   cov 649.465149
## 11   transcript_id STRG.6.1    reference_id gp05  cov 3369.177979
## 13   transcript_id STRG.7.1    reference_id gp06  cov 2390.431641
## 15   transcript_id STRG.8.1    reference_id gp07   cov 553.794983
## 17   transcript_id STRG.9.1    reference_id gp08    cov 52.077705
## 19  transcript_id STRG.10.1    reference_id gp09    cov 90.858253
## 21  transcript_id STRG.11.1    reference_id parA   cov 273.893127
## 23  transcript_id STRG.12.1    reference_id gp11  cov 3966.040771
## 25  transcript_id STRG.13.1    reference_id gp12   cov 167.085022
## 27  transcript_id STRG.14.1   reference_id relB2  cov 1682.772461
## 29  transcript_id STRG.15.1   reference_id relE2   cov 352.163391
## 31  transcript_id STRG.16.1  reference_id dnaB2a   cov 328.654053
##                    V13                V14
## 1    FPKM 47755.140625   TPM 27700.468750
## 3    FPKM 13444.684570    TPM 7798.617188
## 5    FPKM 10288.027344    TPM 5967.591797
## 7    FPKM 17266.701172   TPM 10015.586914
## 9    FPKM 75962.578125   TPM 44062.250000
## 11  FPKM 394064.937500  TPM 228578.187500
## 13  FPKM 279589.062500  TPM 162176.218750
## 15   FPKM 64772.828125   TPM 37571.617188
## 17    FPKM 6091.099609    TPM 3533.154785
## 19   FPKM 10626.939453    TPM 6164.178711
## 21   FPKM 32035.019531   TPM 18581.978516
## 23  FPKM 463875.062500  TPM 269071.687500
## 25   FPKM 19542.554688   TPM 11335.700195
## 27  FPKM 196820.000000  TPM 114165.851562
## 29   FPKM 41189.644531   TPM 23892.138672
## 31   FPKM 38439.953125   TPM 22297.173828
##
## $`./result_stringtie_deduplicated_Cxq_NG_J03_ov_01_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.15
##                         V10                  V11             V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b   cov 72.282608
## 3    transcript_id STRG.2.1   reference_id is110   cov 57.345627
## 5    transcript_id STRG.3.1   reference_id dnaB1    cov 8.327056
## 7    transcript_id STRG.4.1   reference_id relE1    cov 4.182709
## 9    transcript_id STRG.5.1   reference_id relB1   cov 25.166637
## 11   transcript_id STRG.6.1    reference_id gp05  cov 417.932678
## 13   transcript_id STRG.7.1    reference_id gp06  cov 147.327438
## 15   transcript_id STRG.8.1    reference_id gp07   cov 15.087370
## 17   transcript_id STRG.9.1    reference_id gp08    cov 0.847328
## 19  transcript_id STRG.10.1    reference_id gp09    cov 0.450777
## 21  transcript_id STRG.11.1    reference_id parA   cov 33.903816
## 23  transcript_id STRG.12.1    reference_id gp11  cov 307.344086
## 25  transcript_id STRG.13.1   reference_id relB2  cov 110.203751
## 27  transcript_id STRG.14.1   reference_id relE2   cov 51.666904
## 29  transcript_id STRG.15.1  reference_id dnaB2a   cov 37.613514
##                    V13                V14
## 1   FPKM 108923.328125   TPM 55711.949219
## 3    FPKM 86414.648438   TPM 44199.246094
## 5    FPKM 12548.117188    TPM 6418.093262
## 7     FPKM 6302.962891    TPM 3223.830566
## 9    FPKM 37923.835938   TPM 19397.230469
## 11  FPKM 629786.562500  TPM 322122.343750
## 13  FPKM 222009.062500  TPM 113552.890625
## 15   FPKM 22735.296875   TPM 11628.617188
## 17    FPKM 1276.846313     TPM 653.079590
## 19     FPKM 679.279968     TPM 347.437164
## 21   FPKM 51089.972656   TPM 26131.425781
## 23  FPKM 463139.625000  TPM 236886.015625
## 25  FPKM 166067.046875   TPM 84939.742188
## 27   FPKM 77857.328125   TPM 39822.359375
## 29   FPKM 56680.152344   TPM 28990.681641
##
## $`./result_stringtie_deduplicated_Cxq_NG_J03_ov_02_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##      V1        V2         V3   V4   V5   V6 V7 V8              V9
## 1  pWCP StringTie transcript    1  138 1000  +  .  gene_id STRG.1
## 3  pWCP StringTie transcript  226 1174 1000  +  .  gene_id STRG.2
## 5  pWCP StringTie transcript 1381 1879 1000  +  .  gene_id STRG.3
## 7  pWCP StringTie transcript 1875 2184 1000  +  .  gene_id STRG.4
## 9  pWCP StringTie transcript 2164 2398 1000  +  .  gene_id STRG.5
## 11 pWCP StringTie transcript 2484 2691 1000  +  .  gene_id STRG.6
## 13 pWCP StringTie transcript 2760 3834 1000  +  .  gene_id STRG.7
## 15 pWCP StringTie transcript 4010 5165 1000  +  .  gene_id STRG.8
## 17 pWCP StringTie transcript 5209 5470 1000  +  .  gene_id STRG.9
## 19 pWCP StringTie transcript 5450 5642 1000  +  . gene_id STRG.10
## 21 pWCP StringTie transcript 5709 6363 1000  +  . gene_id STRG.11
## 23 pWCP StringTie transcript 6528 7239 1000  +  . gene_id STRG.12
## 25 pWCP StringTie transcript 7367 8060 1000  +  . gene_id STRG.13
## 27 pWCP StringTie transcript 8171 8402 1000  +  . gene_id STRG.14
## 29 pWCP StringTie transcript 8377 8644 1000  +  . gene_id STRG.15
## 31 pWCP StringTie transcript 8859 9228 1000  +  . gene_id STRG.16
##                         V10                  V11             V12
## 1    transcript_id STRG.1.1  reference_id dnaB2b   cov 21.311596
## 3    transcript_id STRG.2.1   reference_id is110   cov 53.584827
## 5    transcript_id STRG.3.1   reference_id dnaB1   cov 14.795350
## 7    transcript_id STRG.4.1   reference_id relE1   cov 19.196732
## 9    transcript_id STRG.5.1   reference_id relB1   cov 37.945251
## 11   transcript_id STRG.6.1    reference_id gp05  cov 264.812500
## 13   transcript_id STRG.7.1    reference_id gp06  cov 287.538605
## 15   transcript_id STRG.8.1    reference_id gp07   cov 60.936852
## 17   transcript_id STRG.9.1    reference_id gp08   cov 11.508149
## 19  transcript_id STRG.10.1    reference_id gp09   cov 16.735052
## 21  transcript_id STRG.11.1    reference_id parA   cov 35.384731
## 23  transcript_id STRG.12.1    reference_id gp11  cov 332.514038
## 25  transcript_id STRG.13.1    reference_id gp12   cov 21.750721
## 27  transcript_id STRG.14.1   reference_id relB2  cov 112.786636
## 29  transcript_id STRG.15.1   reference_id relE2   cov 37.807831
## 31  transcript_id STRG.16.1  reference_id dnaB2a   cov 32.708107
##                    V13                V14
## 1    FPKM 23534.630859   TPM 15554.962891
## 3    FPKM 59174.312500   TPM 39110.632812
## 5    FPKM 16338.667969   TPM 10798.868164
## 7    FPKM 21199.162109   TPM 14011.360352
## 9    FPKM 41903.355469   TPM 27695.578125
## 11  FPKM 292435.343750  TPM 193282.031250
## 13  FPKM 317532.062500  TPM 209869.406250
## 15   FPKM 67293.234375   TPM 44476.746094
## 17   FPKM 12708.576172    TPM 8399.597656
## 19   FPKM 18480.701172   TPM 12214.623047
## 21   FPKM 39075.746094   TPM 25826.699219
## 23  FPKM 367198.906250  TPM 242696.203125
## 25   FPKM 24019.560547   TPM 15875.471680
## 27  FPKM 124551.523438   TPM 82321.000000
## 29   FPKM 41751.601562   TPM 27595.277344
## 31   FPKM 36119.921875   TPM 23873.076172
Data formatting
# Extract the columns of interest from each dataframe
myfiles_extracted <- lapply(myfiles, function(df) {
  df[, c("V1", "V4", "V5", "V11", "V12", "V13", "V14")]
})

myfiles_extracted <- lapply(myfiles_extracted, function(df) {
  # Remove “reference_id” from column V11
  df$V11 <- gsub("reference_id ", "", df$V11)

  # Set column V11 as rownames
  rownames(df) <- df$V11

  return(df)

})

myfiles_extracted <- lapply(myfiles_extracted, function(df) {
  # Remove text prefixes in cells
  df$V12 <- gsub("cov ", "", df$V12)
  df$V13 <- gsub("FPKM ", "", df$V13)
  df$V14 <- gsub("TPM ", "", df$V14)

  return(df)
})

myfiles_extracted <- lapply(myfiles_extracted, function(df) {
  colnames(df) <- c("Ref", "Start", "End", "ID", "Coverage", "FPKM", "TPM")
  return(df)
})

myfiles_extracted <- lapply(myfiles_extracted, function(df) {
  df[, !(names(df) %in% "ID"), drop = FALSE]
})

head(myfiles_extracted)
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_10_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End    Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138  267.891296  145836.500000   82594.851562
##  is110  pWCP   226 1174   34.983139   19044.359375   10785.820312
##  dnaB1  pWCP  1381 1879  108.479362   59054.742188   33445.792969
##  relE1  pWCP  1875 2184   45.236591   24626.207031   13947.111328
##  relB1  pWCP  2164 2398   94.227463   51296.191406   29051.722656
##  gp05   pWCP  2484 2691  841.379822  458036.093750  259409.859375
##  gp06   pWCP  2760 3834  413.470703  225088.000000  127479.132812
##  gp07   pWCP  4010 5165  264.941162  144230.484375   81685.281250
##  gp08   pWCP  5209 5470   21.259481   11573.381836    6554.612793
##  gp09   pWCP  5450 5642   29.979359   16320.369141    9243.080078
##  parA   pWCP  5709 6363   73.819847   40186.554688   22759.751953
##  gp11   pWCP  6528 7239  481.095520  261902.078125  148328.875000
##  gp12   pWCP  7367 8060   39.585014   21549.560547   12204.646484
##  relB2  pWCP  8171 8402  174.390900   94936.117188   53767.292969
##  relE2  pWCP  8377 8644   75.273544   40977.925781   23207.947266
##  dnaB2a pWCP  8859 9228  259.472961  141253.671875   79999.351562
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_11_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End     Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138   444.652161   71202.289062   40760.542969
##  is110  pWCP   226 1174   185.578506   29716.742188   17011.681641
##  dnaB1  pWCP  1381 1879   168.853806   27038.611328   15478.554688
##  relE1  pWCP  1875 2184   174.541260   27949.345703   15999.914062
##  relB1  pWCP  2164 2398   572.345398   91649.851562   52465.976562
##  gp05   pWCP  2484 2691  2177.298096  348651.406250  199589.390625
##  gp06   pWCP  2760 3834  1297.450195  207761.093750  118935.156250
##  gp07   pWCP  4010 5165   580.149658   92899.539062   53181.375000
##  gp08   pWCP  5209 5470    57.448528    9199.250977    5266.213379
##  gp09   pWCP  5450 5642   106.318573   17024.826172    9746.051758
##  parA   pWCP  5709 6363   224.522141   35952.800781   20581.580078
##  gp11   pWCP  6528 7239  2780.412842  445228.343750  254875.937500
##  gp12   pWCP  7367 8060   164.505768   26342.359375   15079.976562
##  relB2  pWCP  8171 8402  1213.079102  194250.734375  111200.984375
##  relE2  pWCP  8377 8644   308.517395   49402.988281   28281.291016
##  dnaB2a pWCP  8859 9228   366.937836   58757.867188   33636.593750
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_13_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End     Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138   436.340607   67570.718750   37998.355469
##  is110  pWCP   226 1174   133.500534   20673.589844   11625.782227
##  dnaB1  pWCP  1381 1879   132.032883   20446.312500   11497.972656
##  relE1  pWCP  1875 2184   108.530441   16806.777344    9451.282227
##  relB1  pWCP  2164 2398   313.838928   48600.382812   27330.400391
##  gp05   pWCP  2484 2691  3364.014404  520943.656250  292952.375000
##  gp06   pWCP  2760 3834  1521.172119  235565.265625  132470.000000
##  gp07   pWCP  4010 5165   544.254333   84281.992188   47395.933594
##  gp08   pWCP  5209 5470    61.304840    9493.528320    5338.680664
##  gp09   pWCP  5450 5642    83.316742   12902.242188    7255.568848
##  parA   pWCP  5709 6363   215.438171   33362.265625   18761.251953
##  gp11   pWCP  6528 7239  2861.283691  443091.906250  249172.484375
##  gp12   pWCP  7367 8060   118.616714   18368.714844   10329.636719
##  relB2  pWCP  8171 8402   997.832397  154522.062500   86895.398438
##  relE2  pWCP  8377 8644   227.268204   35194.238281   19791.460938
##  dnaB2a pWCP  8859 9228   307.251373   47580.253906   26756.726562
##
## $`./result_stringtie_deduplicated_Cxq_NG_J01_ov_14_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End     Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138   408.297089   47755.140625   27700.468750
##  is110  pWCP   226 1174   114.949417   13444.684570    7798.617188
##  dnaB1  pWCP  1381 1879    87.960617   10288.027344    5967.591797
##  relE1  pWCP  1875 2184   147.626923   17266.701172   10015.586914
##  relB1  pWCP  2164 2398   649.465149   75962.578125   44062.250000
##  gp05   pWCP  2484 2691  3369.177979  394064.937500  228578.187500
##  gp06   pWCP  2760 3834  2390.431641  279589.062500  162176.218750
##  gp07   pWCP  4010 5165   553.794983   64772.828125   37571.617188
##  gp08   pWCP  5209 5470    52.077705    6091.099609    3533.154785
##  gp09   pWCP  5450 5642    90.858253   10626.939453    6164.178711
##  parA   pWCP  5709 6363   273.893127   32035.019531   18581.978516
##  gp11   pWCP  6528 7239  3966.040771  463875.062500  269071.687500
##  gp12   pWCP  7367 8060   167.085022   19542.554688   11335.700195
##  relB2  pWCP  8171 8402  1682.772461  196820.000000  114165.851562
##  relE2  pWCP  8377 8644   352.163391   41189.644531   23892.138672
##  dnaB2a pWCP  8859 9228   328.654053   38439.953125   22297.173828
##
## $`./result_stringtie_deduplicated_Cxq_NG_J03_ov_01_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End    Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138   72.282608  108923.328125   55711.949219
##  is110  pWCP   226 1174   57.345627   86414.648438   44199.246094
##  dnaB1  pWCP  1381 1879    8.327056   12548.117188    6418.093262
##  relE1  pWCP  1875 2184    4.182709    6302.962891    3223.830566
##  relB1  pWCP  2164 2398   25.166637   37923.835938   19397.230469
##  gp05   pWCP  2484 2691  417.932678  629786.562500  322122.343750
##  gp06   pWCP  2760 3834  147.327438  222009.062500  113552.890625
##  gp07   pWCP  4010 5165   15.087370   22735.296875   11628.617188
##  gp08   pWCP  5209 5470    0.847328    1276.846313     653.079590
##  gp09   pWCP  5450 5642    0.450777     679.279968     347.437164
##  parA   pWCP  5709 6363   33.903816   51089.972656   26131.425781
##  gp11   pWCP  6528 7239  307.344086  463139.625000  236886.015625
##  relB2  pWCP  8171 8402  110.203751  166067.046875   84939.742188
##  relE2  pWCP  8377 8644   51.666904   77857.328125   39822.359375
##  dnaB2a pWCP  8859 9228   37.613514   56680.152344   28990.681641
##
## $`./result_stringtie_deduplicated_Cxq_NG_J03_ov_02_R1_seqkit_trim_bowtie2_sorted.bam.filtered.bam.txt`
##          Ref Start  End    Coverage           FPKM            TPM
##  dnaB2b pWCP     1  138   21.311596   23534.630859   15554.962891
##  is110  pWCP   226 1174   53.584827   59174.312500   39110.632812
##  dnaB1  pWCP  1381 1879   14.795350   16338.667969   10798.868164
##  relE1  pWCP  1875 2184   19.196732   21199.162109   14011.360352
##  relB1  pWCP  2164 2398   37.945251   41903.355469   27695.578125
##  gp05   pWCP  2484 2691  264.812500  292435.343750  193282.031250
##  gp06   pWCP  2760 3834  287.538605  317532.062500  209869.406250
##  gp07   pWCP  4010 5165   60.936852   67293.234375   44476.746094
##  gp08   pWCP  5209 5470   11.508149   12708.576172    8399.597656
##  gp09   pWCP  5450 5642   16.735052   18480.701172   12214.623047
##  parA   pWCP  5709 6363   35.384731   39075.746094   25826.699219
##  gp11   pWCP  6528 7239  332.514038  367198.906250  242696.203125
##  gp12   pWCP  7367 8060   21.750721   24019.560547   15875.471680
##  relB2  pWCP  8171 8402  112.786636  124551.523438   82321.000000
##  relE2  pWCP  8377 8644   37.807831   41751.601562   27595.277344
##  dnaB2a pWCP  8859 9228   32.708107   36119.921875   23873.076172
library(dplyr)
library(tidyr)

# Transform each DataFrame in the list

myfiles_extracted2 <- Map(function(df, sample_name) {
  # 1. Extract the row names into a column named “Gene”
  df$Gene <- rownames(df)

  # 2. Remove the rownames
  rownames(df) <- NULL

  # 3. Convert numeric columns
  df$Coverage <- as.numeric(df$Coverage)
  df$FPKM     <- as.numeric(df$FPKM)
  df$TPM      <- as.numeric(df$TPM)

  # 4. Add the sample file name into a column named “Sample”
  df$Sample <- sample_name

  return(df)

}, myfiles_extracted, names(myfiles_extracted))

# 5. Combine into a single dataframe
combined_df <- bind_rows(myfiles_extracted2)

combined_df$Sample <- combined_df$Sample %>%
  gsub("^\\.\\/result_stringtie_deduplicated_", "", .) %>%
  gsub("_R1_seqkit_trim_bowtie2_sorted\\.bam\\.filtered\\.bam\\.txt$", "", .)
Merge dnaB2 fragments (because of circularity plasmid is cut inside dnaB2) and pre process data.
library(dplyr)
library(stringr)

# 0) Clean spaces in Gene
combined_df <- combined_df %>%
  dplyr::mutate(Gene = trimws(Gene))

# 1) Merge dnaB2a + dnaB2b into one "Dnab-2" per Sample (region forced)
parts <- c("dnaB2a", "dnaB2b")

dnaB2_merged <- combined_df %>%
  dplyr::filter(Gene %in% parts) %>%
  dplyr::group_by(Sample) %>%
  dplyr::summarise(
    Ref      = dplyr::first(Ref),
    Start    = 8859L,
    End      = 138L,
    Coverage = mean(Coverage, na.rm = TRUE),
    FPKM     = mean(FPKM, na.rm = TRUE),
    TPM      = mean(TPM, na.rm = TRUE),
    Gene     = "Dnab-2",
    .groups  = "drop"
  )

other_genes <- combined_df %>%
  dplyr::filter(!Gene %in% parts)

combined_df_merged <- dplyr::bind_rows(other_genes, dnaB2_merged)

# 2) Mapping table for renaming to qPCR labels
map_df <- tibble::tibble(
  Gene_old = c("dnaB1", "Dnab-2", "gp05", "gp06", "gp07", "gp08", "gp09",
               "parA", "gp11", "gp12", "relB1", "relB2", "relE1", "relE2", "is110"),
  Gene_new = c("Dnab-1 (GP02)", "Dnab-2 (GP02)", "GP05", "GP06", "GP07", "GP08", "GP09",
               "ParA-like", "GP11", "GP12", "RelB_1", "RelB_2", "RelE_1", "RelE_2", "IS110")
)

# 3) Apply the renaming safely (and drop helper column)
combined_df_renamed <- combined_df_merged %>%
  dplyr::mutate(Gene = trimws(Gene)) %>%
  dplyr::left_join(map_df, by = c("Gene" = "Gene_old")) %>%
  dplyr::mutate(Gene = dplyr::coalesce(Gene_new, Gene)) %>%
  dplyr::select(-Gene_new)

# 4) Set plotting order
final_order <- c(
  "Dnab-1 (GP02)",
  "IS110",
  "Dnab-2 (GP02)",
  "GP05",
  "GP06",
  "GP07",
  "GP08",
  "GP09",
  "ParA-like",
  "GP11",
  "GP12",
  "RelB_1",
  "RelE_1",
  "RelB_2",
  "RelE_2"
)

combined_df_renamed <- combined_df_renamed %>%
  dplyr::mutate(Gene = factor(Gene, levels = final_order))
Sample batch characterization
library(dplyr)
library(stringr)

combined_df_tagged <- combined_df_renamed %>%
  # extract J01, J03, J07, J14 from the Sample string if present
  mutate(
    Batch = str_extract(Sample, "J(01|03|07|14)"),
    # if you prefer to label non-matching samples instead of NA, uncomment:
    # Batch = if_else(is.na(Batch), "Other", Batch)
  )

# (Optional) make it an ordered factor
combined_df_tagged <- combined_df_tagged %>%
  mutate(Batch = factor(Batch, levels = c("J01", "J03", "J07", "J14", "Other")))
Inter-group statistics
GLM with gamma distribution on TPM distribution across the different aging batchs
library(dplyr)
library(stringr)
library(purrr)
library(emmeans)
## Welcome to emmeans.
## Caution: You lose important information if you filter this package's results.
## See '? untidy'
library(glmmTMB)
library(openxlsx)
library(tibble)

# -------------------------
# 0) Settings & data input
# -------------------------

# Your batch levels and preferred order
batch_levels <- c("J01","J03","J07","J14")

# 1) Prepare analysis table: average duplicates per (Gene, Sample), keep ordered Batch
dat <- combined_df_tagged %>%
  dplyr::filter(!is.na(Batch), Batch %in% batch_levels) %>%
  dplyr::group_by(Gene, Sample, Batch) %>%
  dplyr::summarise(TPM = mean(TPM, na.rm = TRUE), .groups = "drop") %>%
  dplyr::mutate(Batch = factor(Batch, levels = batch_levels))

# Small positive epsilon for Gamma model (strictly > 0)
EPS <- 1e-3

# List of genes to analyse
genes <- sort(unique(dat$Gene))

# Pairwise Batch comparisons (Bonferroni)

fit_one_gene <- function(g) {
  df <- dat %>% dplyr::filter(Gene == g)

  # Need >= 2 levels of Batch and enough rows
  if (n_distinct(df$Batch) < 2L || nrow(df) < 4L) return(list(overall = NULL, pairs = NULL))

  # Response for Gamma (strictly positive)
  df <- df %>% dplyr::mutate(TPM_gamma = TPM + EPS)

  # ---- MODEL ----
  # Plain GLM
  mod <- glmmTMB::glmmTMB(TPM_gamma ~ Batch,
                          data = df, family = Gamma(link = "log"))

  # (Optional) If you have a replicate/group factor, use GLMM:
  # mod <- glmmTMB::glmmTMB(TPM_gamma ~ Batch + (1 | Group),
  #                         data = df, family = Gamma(link = "log"))

  # Null (intercept-only) for LRT
  mod0 <- glmmTMB::glmmTMB(TPM_gamma ~ 1, data = df, family = Gamma(link = "log"))

  # LRT for overall Batch effect
  lrt <- as.data.frame(anova(mod, mod0))
  # lrt has two rows; the comparison is in the second row
  overall <- tibble::tibble(
    Gene        = g,
    n           = nrow(df),
    logLik_full = lrt$logLik[1],
    logLik_null = lrt$logLik[2],
    AIC_full    = lrt$AIC[1],
    AIC_null    = lrt$AIC[2],
    Chisq       = lrt$Chisq[2],
    Df          = lrt$Df[2],
    p_overall   = lrt$`Pr(>Chisq)`[2]
  )

  # emmeans on the link scale, then pairwise with Bonferroni (as in your qPCR)
  emm  <- emmeans::emmeans(mod, ~ Batch)  # type="link" by default matches model scale
  pr   <- pairs(emm, adjust = "bonferroni")
  pairs_df <- as.data.frame(pr)

  # Normalise column names (t.ratio vs z.ratio) and parse contrast
  if ("t.ratio" %in% names(pairs_df) && !("z.ratio" %in% names(pairs_df))) {
    names(pairs_df)[names(pairs_df) == "t.ratio"] <- "z.ratio"
  }
  if (!("df" %in% names(pairs_df))) pairs_df$df <- NA_real_

  pairs_out <- pairs_df %>%
    dplyr::mutate(
      Gene   = g,
      batch1 = stringr::str_trim(stringr::str_extract(contrast, "^[^-]+")),
      batch2 = stringr::str_trim(stringr::str_extract(contrast, "(?<=- ).+$")),
      p.signif = cut(p.value,
                     breaks = c(-Inf, 0.001, 0.01, 0.05, Inf),
                     labels = c("***", "**", "*", "ns"))
    ) %>%
    dplyr::select(Gene, contrast, batch1, batch2,
                  estimate, SE, df, z.ratio, p.value, p.signif)

  list(overall = overall, pairs = pairs_out)
}

res_list <- purrr::map(genes, ~ tryCatch(fit_one_gene(.x),
                                         error = function(e) { message("Gene failed: ", .x, " | ", e$message); list(overall=NULL, pairs=NULL) }))

# Bind rows
overall_tbl <- purrr::map_dfr(res_list, "overall")
pairs_tbl   <- purrr::map_dfr(res_list, "pairs")

# BH adjust across genes for the overall test (global multiple testing)
overall_tbl <- overall_tbl %>%
  dplyr::mutate(p_overall_BH = p.adjust(p_overall, method = "BH")) %>%
  dplyr::arrange(p_overall_BH)

# Optional: add sample counts per Gene × Batch (handy QC sheet)
sizes_tbl <- dat %>%
  dplyr::count(Gene, Batch, name = "n") %>%
  tidyr::pivot_wider(names_from = Batch, values_from = n, values_fill = 0) %>%
  dplyr::arrange(Gene)

# -------------------------
# 3) Export to Excel
# -------------------------
wb <- openxlsx::createWorkbook()
openxlsx::addWorksheet(wb, "Overall_GLM_Batch")
openxlsx::addWorksheet(wb, "Pairwise_Batch")
openxlsx::addWorksheet(wb, "Group_sizes")

openxlsx::writeData(wb, "Overall_GLM_Batch", overall_tbl)
openxlsx::writeData(wb, "Pairwise_Batch", pairs_tbl)
openxlsx::writeData(wb, "Group_sizes", sizes_tbl)

openxlsx::saveWorkbook(wb, "./Output/RNAseq_TPM_GammaGLM_Batch_posthoc.xlsx", overwrite = TRUE)
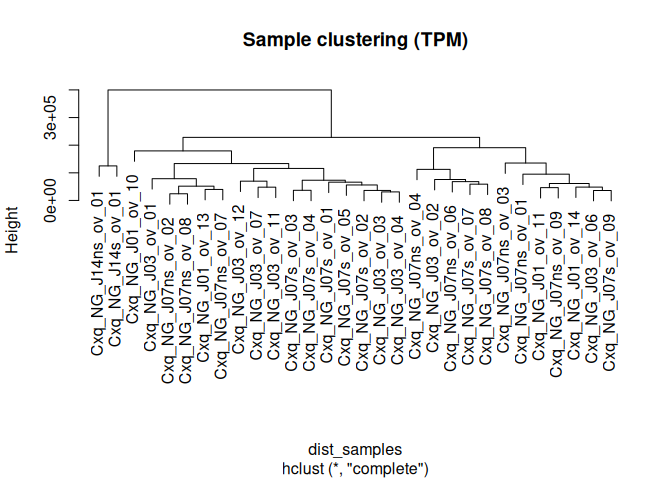
Dendogram
library(dplyr)
library(tidyr)

tpm_matrix <- combined_df_renamed %>%
  dplyr::select(Gene, Sample, TPM) %>%  # explicitly use dplyr::select
  tidyr::pivot_wider(names_from = Sample, values_from = TPM) %>%
  as.data.frame()


# set gene names as rownames
rownames(tpm_matrix) <- tpm_matrix$Gene
tpm_matrix$Gene <- NULL

# samples must be rows → transpose
sample_matrix <- t(tpm_matrix)

# hierarchical clustering
dist_samples <- dist(sample_matrix, method = "euclidean")
hc_samples <- hclust(dist_samples, method = "complete")

plot(hc_samples, main = "Sample clustering (TPM)")
Dendogram + heatmap
library(reshape2)
##
## Attaching package: 'reshape2'

## The following object is masked from 'package:tidyr':
##
##     smiths
library(ggplot2)
library(ggdendro)
library(grid)

# reorder matrix according to clustering
reordered <- sample_matrix[hc_samples$order, ]

# melt for ggplot
melted <- melt(reordered)

heatmap_plot <- ggplot(melted, aes(Var2, Var1, fill = value)) +
  geom_tile(color = "white") +
  scale_fill_gradient(low = "white", high = "red") +
  theme_minimal() +
  theme(axis.text.x = element_text(angle = 90, size = 8),
        axis.title = element_blank()) +
  coord_fixed()

dendro_plot <- ggdendrogram(hc_samples, rotate = TRUE)

grid.newpage()
print(heatmap_plot, vp = viewport(x = 0.35, y = 0.5, width = 0.7, height = 1))
print(dendro_plot, vp = viewport(x = 0.85, y = 0.5, width = 0.25, height = 0.9))
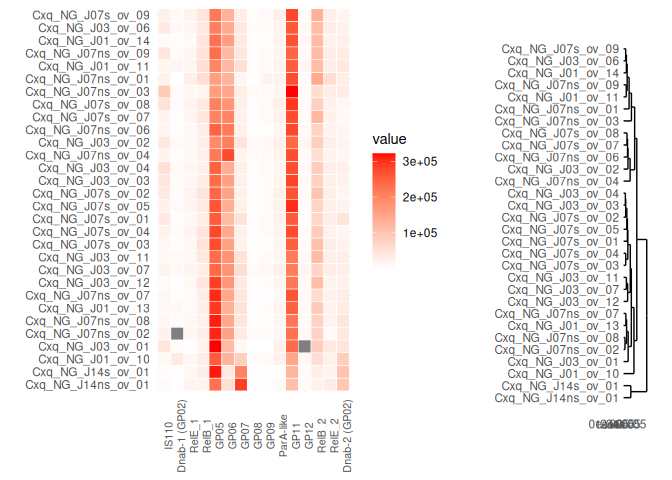 The two grey squares
correspond to values of zero and were colored white in the main text
figure.
Define clusters
# hc_samples
clusters <- cutree(hc_samples, h = 3e5)  # Cut where the distance is <= 3e5
print(clusters)
##   Cxq_NG_J01_ov_10   Cxq_NG_J01_ov_11   Cxq_NG_J01_ov_13   Cxq_NG_J01_ov_14
##                  1                  1                  1                  1
##   Cxq_NG_J03_ov_01   Cxq_NG_J03_ov_02   Cxq_NG_J03_ov_03   Cxq_NG_J03_ov_04
##                  1                  1                  1                  1
##   Cxq_NG_J03_ov_06   Cxq_NG_J03_ov_07   Cxq_NG_J03_ov_11   Cxq_NG_J03_ov_12
##                  1                  1                  1                  1
## Cxq_NG_J07ns_ov_01 Cxq_NG_J07ns_ov_02 Cxq_NG_J07ns_ov_03 Cxq_NG_J07ns_ov_04
##                  1                  1                  1                  1
## Cxq_NG_J07ns_ov_06 Cxq_NG_J07ns_ov_07 Cxq_NG_J07ns_ov_08 Cxq_NG_J07ns_ov_09
##                  1                  1                  1                  1
##  Cxq_NG_J07s_ov_01  Cxq_NG_J07s_ov_02  Cxq_NG_J07s_ov_03  Cxq_NG_J07s_ov_04
##                  1                  1                  1                  1
##  Cxq_NG_J07s_ov_05  Cxq_NG_J07s_ov_07  Cxq_NG_J07s_ov_08  Cxq_NG_J07s_ov_09
##                  1                  1                  1                  1
## Cxq_NG_J14ns_ov_01  Cxq_NG_J14s_ov_01
##                  2                  2
Intra-group statistics
Boxplot preparation
G2 <- c("Cxq_NG_J14ns_ov_01", "Cxq_NG_J14s_ov_01")

G1 <- c(
  "Cxq_NG_J01_ov_10", "Cxq_NG_J03_ov_01", "Cxq_NG_J01_ov_11", "Cxq_NG_J01_ov_13", "Cxq_NG_J01_ov_14",
  "Cxq_NG_J03_ov_02", "Cxq_NG_J03_ov_03", "Cxq_NG_J03_ov_04",
  "Cxq_NG_J03_ov_06", "Cxq_NG_J03_ov_07",
  "Cxq_NG_J03_ov_11", "Cxq_NG_J03_ov_12",
  "Cxq_NG_J07ns_ov_01", "Cxq_NG_J07ns_ov_02", "Cxq_NG_J07ns_ov_03",
  "Cxq_NG_J07ns_ov_04", "Cxq_NG_J07ns_ov_06", "Cxq_NG_J07ns_ov_07",
  "Cxq_NG_J07ns_ov_08", "Cxq_NG_J07ns_ov_09",
  "Cxq_NG_J07s_ov_01", "Cxq_NG_J07s_ov_02", "Cxq_NG_J07s_ov_03",
  "Cxq_NG_J07s_ov_04", "Cxq_NG_J07s_ov_05",
  "Cxq_NG_J07s_ov_07", "Cxq_NG_J07s_ov_08", "Cxq_NG_J07s_ov_09"
)

combined_df_renamed$Group <- case_when(
  combined_df_renamed$Sample %in% G2       ~ "G2",
  combined_df_renamed$Sample %in% G1       ~ "G1",
  TRUE                             ~ "Unknown"
)
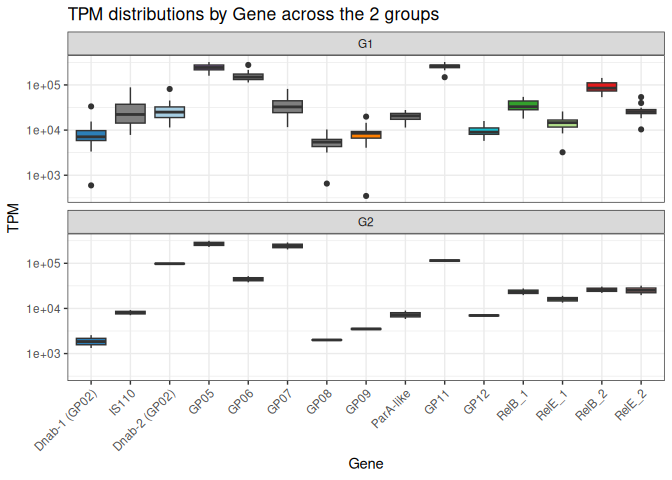
Boxplot by group
library(ggplot2)
library(dplyr)

# 2) Custom color palette (paired hues for linked genes from qPCR analyses)
gene_colors <- c(
  # GP02 pair: blue (dark/light)
  "Dnab-1 (GP02)" = "#2C7FB8",  # dark/medium blue
  "Dnab-2 (GP02)" = "#A6CEE3",  # light blue

  # Distinct colors for the other GPs
  "GP05"          = "#9467BD",  # purple
  "GP09"          = "#FF7F00",  # orange
  "GP11"          = "#8C564B",  # brown
  "GP12"          = "#17BECF",  # teal

  # Rel_1 pair: green (dark/light)
  "RelB_1"        = "#33A02C",  # dark/medium green
  "RelE_1"        = "#B2DF8A",  # light green

  # Rel_2 pair: red (dark/light) — now same-hue gradient
  "RelB_2"        = "#E31A1C",  # strong red
  "RelE_2"        = "#FCA5A5"   # light red (slightly lighter than FB9A99)
)

# TPM boxplots by group, genes on the x-axis
ggplot(combined_df_renamed, aes(x = Gene, y = TPM, fill = Gene)) +
  geom_boxplot() +
  facet_wrap(~ Group, nrow = 2) +
  scale_fill_manual(
    values = gene_colors,
    na.translate = TRUE
  ) +
  scale_y_log10() +
  theme_bw() +
  theme(
    axis.text.x = element_text(angle = 45, hjust = 1),
    legend.position = "none"
  ) +
  labs(
    title = "TPM distributions by Gene across the 2 groups",
    x = "Gene",
    y = "TPM",
  )
library(dplyr)

g1_df <- combined_df_renamed %>%
  filter(Group == "G1") %>%
  mutate(Gene = factor(Gene))

g1_df <- g1_df %>% filter(TPM > 0)
glm_g1 <- glm(
  TPM ~ Gene,
  data = g1_df,
  family = Gamma(link = "log")
)
library(emmeans)

emm_gene <- emmeans(glm_g1, ~ Gene, type = "response")

pairwise_gene <- pairs(
  emm_gene,
  adjust = "Bonferroni"
)

pairwise_gene
##  contrast                            ratio      SE  df null t.ratio p.value
##  (Dnab-1 (GP02)) / IS110            0.3056 0.03150 403    1 -11.492 <0.0001
##  (Dnab-1 (GP02)) / (Dnab-2 (GP02))  0.2993 0.03090 403    1 -11.696 <0.0001
##  (Dnab-1 (GP02)) / GP05             0.0344 0.00354 403    1 -32.681 <0.0001
##  (Dnab-1 (GP02)) / GP06             0.0537 0.00554 403    1 -28.346 <0.0001
##  (Dnab-1 (GP02)) / GP07             0.2393 0.02470 403    1 -13.864 <0.0001
##  (Dnab-1 (GP02)) / GP08             1.5168 0.15600 403    1   4.039  0.0068
##  (Dnab-1 (GP02)) / GP09             1.0151 0.10500 403    1   0.145  1.0000
##  (Dnab-1 (GP02)) / (ParA-like)      0.4150 0.04280 403    1  -8.528 <0.0001
##  (Dnab-1 (GP02)) / GP11             0.0328 0.00338 403    1 -33.132 <0.0001
##  (Dnab-1 (GP02)) / GP12             0.8507 0.08850 403    1  -1.554  1.0000
##  (Dnab-1 (GP02)) / RelB_1           0.2387 0.02460 403    1 -13.889 <0.0001
##  (Dnab-1 (GP02)) / RelE_1           0.5820 0.06000 403    1  -5.247 <0.0001
##  (Dnab-1 (GP02)) / RelB_2           0.0937 0.00967 403    1 -22.950 <0.0001
##  (Dnab-1 (GP02)) / RelE_2           0.3195 0.03290 403    1 -11.064 <0.0001
##  IS110 / (Dnab-2 (GP02))            0.9792 0.10000 403    1  -0.206  1.0000
##  IS110 / GP05                       0.1124 0.01150 403    1 -21.385 <0.0001
##  IS110 / GP06                       0.1758 0.01800 403    1 -17.010 <0.0001
##  IS110 / GP07                       0.7830 0.08000 403    1  -2.394  1.0000
##  IS110 / GP08                       4.9625 0.50700 403    1  15.674 <0.0001
##  IS110 / GP09                       3.3211 0.33900 403    1  11.744 <0.0001
##  IS110 / (ParA-like)                1.3577 0.13900 403    1   2.992  0.3090
##  IS110 / GP11                       0.1073 0.01100 403    1 -21.839 <0.0001
##  IS110 / GP12                       2.7833 0.28700 403    1   9.925 <0.0001
##  IS110 / RelB_1                     0.7810 0.07980 403    1  -2.419  1.0000
##  IS110 / RelE_1                     1.9043 0.19500 403    1   6.302 <0.0001
##  IS110 / RelB_2                     0.3067 0.03130 403    1 -11.564 <0.0001
##  IS110 / RelE_2                     1.0452 0.10700 403    1   0.432  1.0000
##  (Dnab-2 (GP02)) / GP05             0.1148 0.01170 403    1 -21.179 <0.0001
##  (Dnab-2 (GP02)) / GP06             0.1795 0.01830 403    1 -16.804 <0.0001
##  (Dnab-2 (GP02)) / GP07             0.7996 0.08170 403    1  -2.188  1.0000
##  (Dnab-2 (GP02)) / GP08             5.0681 0.51800 403    1  15.880 <0.0001
##  (Dnab-2 (GP02)) / GP09             3.3918 0.34700 403    1  11.950 <0.0001
##  (Dnab-2 (GP02)) / (ParA-like)      1.3866 0.14200 403    1   3.198  0.1568
##  (Dnab-2 (GP02)) / GP11             0.1096 0.01120 403    1 -21.633 <0.0001
##  (Dnab-2 (GP02)) / GP12             2.8426 0.29300 403    1  10.129 <0.0001
##  (Dnab-2 (GP02)) / RelB_1           0.7976 0.08150 403    1  -2.213  1.0000
##  (Dnab-2 (GP02)) / RelE_1           1.9448 0.19900 403    1   6.508 <0.0001
##  (Dnab-2 (GP02)) / RelB_2           0.3132 0.03200 403    1 -11.358 <0.0001
##  (Dnab-2 (GP02)) / RelE_2           1.0674 0.10900 403    1   0.638  1.0000
##  GP05 / GP06                        1.5638 0.16000 403    1   4.375  0.0016
##  GP05 / GP07                        6.9649 0.71200 403    1  18.991 <0.0001
##  GP05 / GP08                       44.1441 4.51000 403    1  37.059 <0.0001
##  GP05 / GP09                       29.5427 3.02000 403    1  33.129 <0.0001
##  GP05 / (ParA-like)                12.0772 1.23000 403    1  24.376 <0.0001
##  GP05 / GP11                        0.9546 0.09760 403    1  -0.454  1.0000
##  GP05 / GP12                       24.7592 2.55000 403    1  31.114 <0.0001
##  GP05 / RelB_1                      6.9474 0.71000 403    1  18.966 <0.0001
##  GP05 / RelE_1                     16.9397 1.73000 403    1  27.687 <0.0001
##  GP05 / RelB_2                      2.7283 0.27900 403    1   9.821 <0.0001
##  GP05 / RelE_2                      9.2973 0.95000 403    1  21.817 <0.0001
##  GP06 / GP07                        4.4538 0.45500 403    1  14.616 <0.0001
##  GP06 / GP08                       28.2286 2.89000 403    1  32.684 <0.0001
##  GP06 / GP09                       18.8915 1.93000 403    1  28.754 <0.0001
##  GP06 / (ParA-like)                 7.7229 0.78900 403    1  20.002 <0.0001
##  GP06 / GP11                        0.6105 0.06240 403    1  -4.829  0.0002
##  GP06 / GP12                       15.8327 1.63000 403    1  26.779 <0.0001
##  GP06 / RelB_1                      4.4426 0.45400 403    1  14.591 <0.0001
##  GP06 / RelE_1                     10.8324 1.11000 403    1  23.312 <0.0001
##  GP06 / RelB_2                      1.7447 0.17800 403    1   5.446 <0.0001
##  GP06 / RelE_2                      5.9453 0.60800 403    1  17.442 <0.0001
##  GP07 / GP08                        6.3381 0.64800 403    1  18.068 <0.0001
##  GP07 / GP09                        4.2417 0.43400 403    1  14.138 <0.0001
##  GP07 / (ParA-like)                 1.7340 0.17700 403    1   5.386 <0.0001
##  GP07 / GP11                        0.1371 0.01400 403    1 -19.445 <0.0001
##  GP07 / GP12                        3.5549 0.36700 403    1  12.297 <0.0001
##  GP07 / RelB_1                      0.9975 0.10200 403    1  -0.025  1.0000
##  GP07 / RelE_1                      2.4322 0.24900 403    1   8.696 <0.0001
##  GP07 / RelB_2                      0.3917 0.04000 403    1  -9.170 <0.0001
##  GP07 / RelE_2                      1.3349 0.13600 403    1   2.826  0.5191
##  GP08 / GP09                        0.6692 0.06840 403    1  -3.930  0.0105
##  GP08 / (ParA-like)                 0.2736 0.02800 403    1 -12.682 <0.0001
##  GP08 / GP11                        0.0216 0.00221 403    1 -37.513 <0.0001
##  GP08 / GP12                        0.5609 0.05790 403    1  -5.606 <0.0001
##  GP08 / RelB_1                      0.1574 0.01610 403    1 -18.093 <0.0001
##  GP08 / RelE_1                      0.3837 0.03920 403    1  -9.372 <0.0001
##  GP08 / RelB_2                      0.0618 0.00632 403    1 -27.238 <0.0001
##  GP08 / RelE_2                      0.2106 0.02150 403    1 -15.242 <0.0001
##  GP09 / (ParA-like)                 0.4088 0.04180 403    1  -8.752 <0.0001
##  GP09 / GP11                        0.0323 0.00330 403    1 -33.583 <0.0001
##  GP09 / GP12                        0.8381 0.08640 403    1  -1.713  1.0000
##  GP09 / RelB_1                      0.2352 0.02400 403    1 -14.163 <0.0001
##  GP09 / RelE_1                      0.5734 0.05860 403    1  -5.442 <0.0001
##  GP09 / RelB_2                      0.0924 0.00944 403    1 -23.308 <0.0001
##  GP09 / RelE_2                      0.3147 0.03220 403    1 -11.312 <0.0001
##  (ParA-like) / GP11                 0.0790 0.00808 403    1 -24.831 <0.0001
##  (ParA-like) / GP12                 2.0501 0.21100 403    1   6.960 <0.0001
##  (ParA-like) / RelB_1               0.5753 0.05880 403    1  -5.410 <0.0001
##  (ParA-like) / RelE_1               1.4026 0.14300 403    1   3.311  0.1066
##  (ParA-like) / RelB_2               0.2259 0.02310 403    1 -14.556 <0.0001
##  (ParA-like) / RelE_2               0.7698 0.07870 403    1  -2.560  1.0000
##  GP11 / GP12                       25.9362 2.68000 403    1  31.564 <0.0001
##  GP11 / RelB_1                      7.2776 0.74400 403    1  19.420 <0.0001
##  GP11 / RelE_1                     17.7450 1.81000 403    1  28.141 <0.0001
##  GP11 / RelB_2                      2.8580 0.29200 403    1  10.275 <0.0001
##  GP11 / RelE_2                      9.7393 0.99500 403    1  22.271 <0.0001
##  GP12 / RelB_1                      0.2806 0.02890 403    1 -12.321 <0.0001
##  GP12 / RelE_1                      0.6842 0.07060 403    1  -3.680  0.0279
##  GP12 / RelB_2                      0.1102 0.01140 403    1 -21.383 <0.0001
##  GP12 / RelE_2                      0.3755 0.03870 403    1  -9.496 <0.0001
##  RelB_1 / RelE_1                    2.4383 0.24900 403    1   8.721 <0.0001
##  RelB_1 / RelB_2                    0.3927 0.04010 403    1  -9.145 <0.0001
##  RelB_1 / RelE_2                    1.3383 0.13700 403    1   2.851  0.4813
##  RelE_1 / RelB_2                    0.1611 0.01650 403    1 -17.866 <0.0001
##  RelE_1 / RelE_2                    0.5488 0.05610 403    1  -5.870 <0.0001
##  RelB_2 / RelE_2                    3.4077 0.34800 403    1  11.996 <0.0001
##
## P value adjustment: bonferroni method for 105 tests
## Tests are performed on the log scale
library(broom)

pairwise_df <- tidy(pairwise_gene)

library(tidyr)

pairwise_df <- pairwise_df %>%
  separate(contrast, into = c("Gene_1", "Gene_2"), sep = " / ")

library(openxlsx)

write.xlsx(
  pairwise_df,
  file = "./Output/G1_Gene_pairwise_TPM_GammaGLM_emmeans.xlsx",
  overwrite = TRUE
)